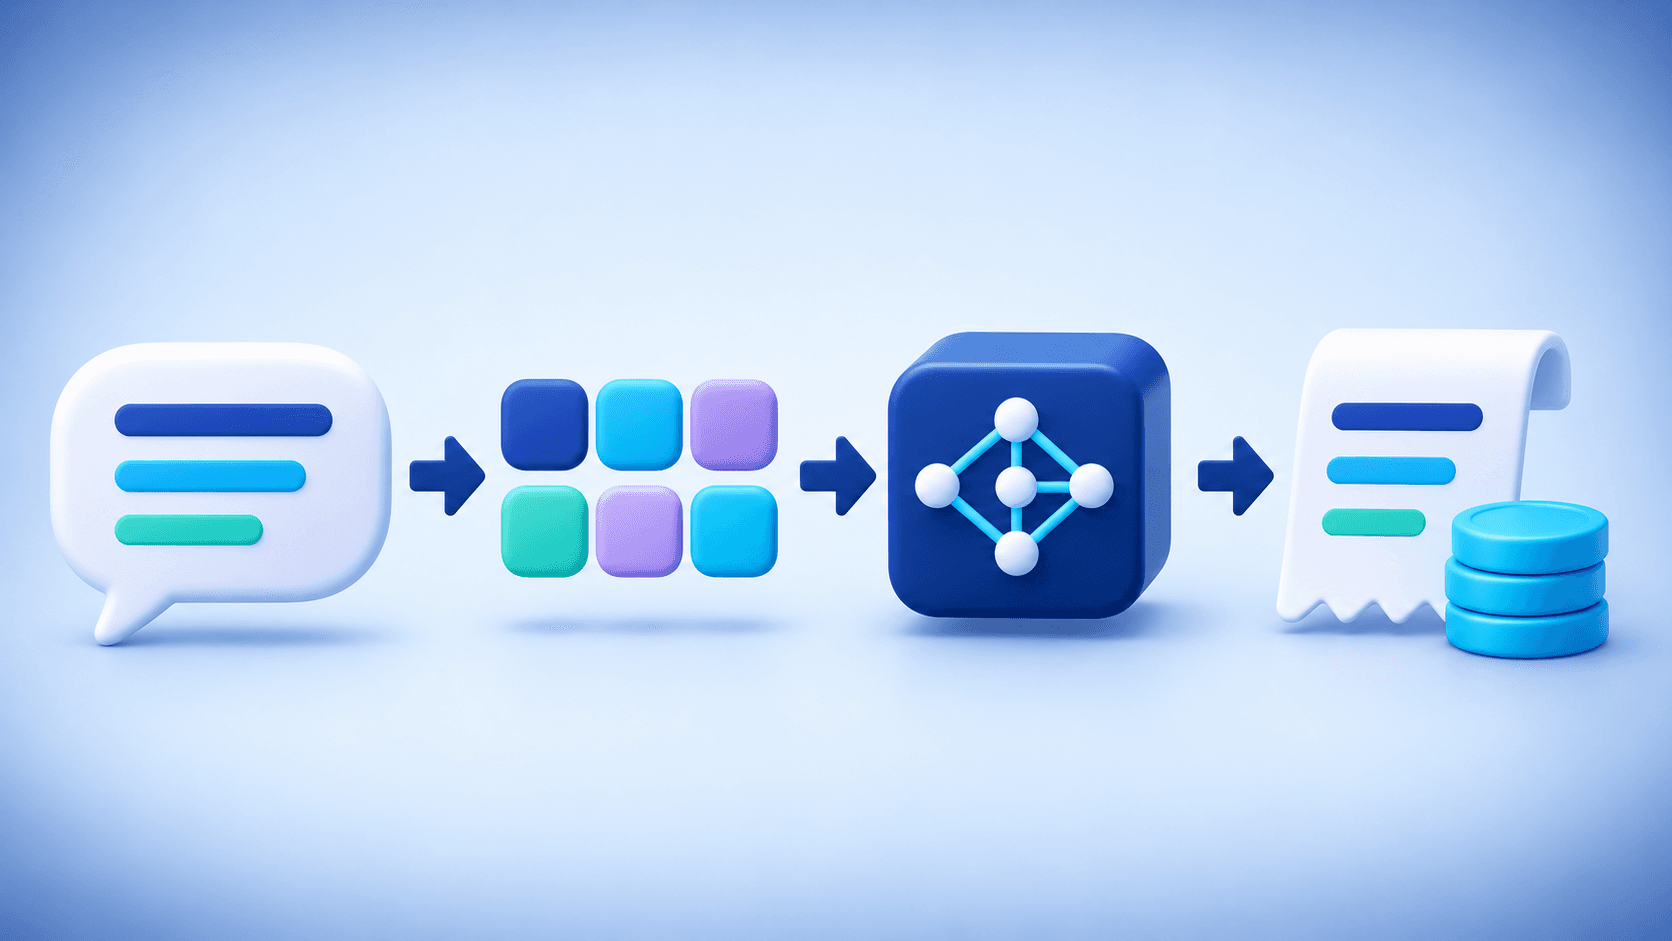
When you ask an AI model a question, the cost is usually not based on the number of words you type. The model first breaks your text into smaller pieces called tokens, processes those tokens, and then generates a response token by token.
That is why two passages with the same word count can use different numbers of tokens. Language, punctuation, numbers, code, and the selected model can all affect how text is split. Understanding tokens makes it easier to estimate why a short chat is inexpensive, why a long document costs more, and how to control usage without sacrificing useful results.
A token is not the same as a word
A token is a small unit that a model processes. It may be a full word, part of a word, punctuation, a number, or a short sequence of characters. There is no universal rule that says one token equals one word.
Token counts also vary by tokenizer and language. Similar-length English and Persian passages may not produce the same count. For a reliable estimate, use the tokenizer provided for the model or check the usage data returned by the API.
Input tokens and output tokens
Input tokens
Input includes everything sent to the model: your latest prompt, system instructions, relevant conversation history, extracted text from uploaded files, retrieved information, and sometimes tool results. A new message can be short while the total input is large because earlier parts of the conversation are sent again.
Output tokens
Output is the content generated by the model. Longer answers normally use more output tokens. Many providers charge different rates for input and output, and output is often more expensive because generation happens step by step.
Some services also list cached input, reasoning tokens, search or code-execution fees, and separate pricing for images, audio, or video. Always check the pricing page for the exact model and feature you plan to use.
The basic cost formula
Input cost = input tokens ÷ 1,000,000 × the model’s input rate
Output cost = output tokens ÷ 1,000,000 × the model’s output rate
Total cost = input cost + output cost + any tool or media fees
A simple example
Imagine a fictional model that charges 1 unit per million input tokens and 4 units per million output tokens. A request uses 10,000 input tokens and produces 2,000 output tokens:
Input: 10,000 ÷ 1,000,000 × 1 = 0.01 units
Output: 2,000 ÷ 1,000,000 × 4 = 0.008 units
Total: 0.018 units
These numbers only demonstrate the calculation. They are not the price of a real model. Provider rates change, so use the current pricing page for actual estimates.
Why long conversations can cost more
To maintain context, the application may send earlier messages along with your new prompt. As a conversation grows, later requests can contain more input tokens. If you are switching to an unrelated topic, starting a fresh chat can avoid repeatedly sending irrelevant history.
What about files, images, audio, and video?
Text files are usually extracted and tokenized. Images may be converted into visual tokens or billed through image-specific units based on size and detail. Audio and video can be priced by duration, quality, or provider-specific units. Some tools also add a separate fee on top of model usage.
Context window versus actual usage
A model’s context window is the maximum amount of information it can consider in one request. It is a capacity limit, not an automatic charge for the entire window. Billing is generally based on the tokens actually processed and generated.
Does an output limit control cost?
A sensible output limit can prevent unnecessarily long answers, but it is usually a maximum rather than a guaranteed amount. A model that finishes earlier may consume fewer output tokens.
Seven practical ways to reduce unnecessary usage
1. Match the model to the task
Routine summaries and short rewrites do not always require the most capable model. Reserve more advanced models for work that genuinely needs deeper reasoning, higher accuracy, or a larger context window.
2. Write a focused prompt
State the goal, audience, constraints, and desired format up front. A clear request reduces the need for repeated revisions.
3. Start a new chat for an unrelated task
When the topic changes completely, a new conversation can prevent irrelevant history from being included again.
4. Clean documents before uploading them
Remove duplicate pages, unrelated appendices, and unnecessary sections. Send only what the model needs.
5. Request an appropriate response length
Ask for five bullets, a 150-word summary, or a compact table when that is all you need.
6. Consolidate revision feedback
Instead of sending many small correction messages, collect the requested changes and send them together.
7. Check the current model price
Similar model names do not imply similar rates. Review input, output, caching, and tool charges on the provider’s official pricing page.
Making a smarter choice in Hoveydai
Hoveydai lets you compare different AI models in one environment. Price is only one part of the decision. Persian and English quality, speed, context capacity, file support, and available tools also matter.
For everyday work, a fast and economical model may be the best fit. For complex analysis, sensitive code, or specialized writing, a more capable model may justify the higher cost. Treat the pricing and model information shown in Hoveydai as the current reference, because provider rates can change.
Final takeaway
Tokens are the bridge between human language and AI computation. The final cost depends on more than the length of your latest question: input, output, conversation history, files, tools, and model choice all play a role.
You do not need to sacrifice quality to control spending. Choosing the right model, writing a clear prompt, managing context, and checking current rates usually make the biggest difference.